Project description
Orquestra Studio
Three coding agents, one request. Orquestra plans, splits the work into tasks, runs the independent ones in parallel, each in its own Git copy, tests, asks an agent from another vendor for a review and integrates one at a time. The person approves the plan and the delivery.
- Role
- Author, personal project
- Period
- Oct 2026
- Status
- in progress
- LLMs and agents
- Node.js
- React
- TypeScript
- Vite
- Git worktrees
- Playwright
- Codex
- Claude Code
- Antigravity
Evidence
Full cycle with the three real CLIs: 4 tasks, 10 calls, 0 failures
Validation on October 19, 2026 in a test repository: Codex plans, Claude Code implements and Antigravity reviews; four integrations with the tests after each one, and 18 of 18 tests at delivery. One review asked for changes, and the second one approved.
Measured.
1.38× parallel speedup with three tasks
Live validation on October 20, 2026, with 2 independent tasks and 1 dependent one: 6 real sessions and 8 of 8 checks. The agents' summed time divided by wall-clock time, on a small test project.
Measured.
121 automated tests passing
Run on October 30, 2026 on the 0.7.1 base: unit and integration tests with real Git, real test commands and simulated agents, with no credentials or quota.
Measured.
The problem
Anyone using more than one coding agent switches between terminals, copies context by hand and has no way to show that the result was tested and reviewed. On bigger projects, splitting the work, the order, the parallelism and the integration all live in the operator’s head.
Orquestra Studio moves that into code: a local dashboard that treats the agents as executors, planners and reviewers, and leaves the person with the two decisions that matter, the plan and the delivery.
The safeguards in the code
What can go wrong with an agent editing files is held in the code, not in the prompt:
- the tests run on the base before any agent, and a broken base stops the run without spending quota;
- an attempt that changes
.env, keys or certificates is discarded before the commit; - agents and tests run without the environment variables that look like secrets;
- the planner and the reviewers are read-only, and commands stay blocked until the person allows them;
- the service listens only on 127.0.0.1 and refuses other origins;
- Orquestra only creates and deletes
orquestra/*branches, and the person’s branch only changes when they apply.
When an agent runs out of quota, login or network, the role passes to the next one in line, and the reason for each model choice is recorded in the session.
On screen
Tap outside the image to close it.
Tap outside the image to close it.
Tap outside the image to close it.
How it works
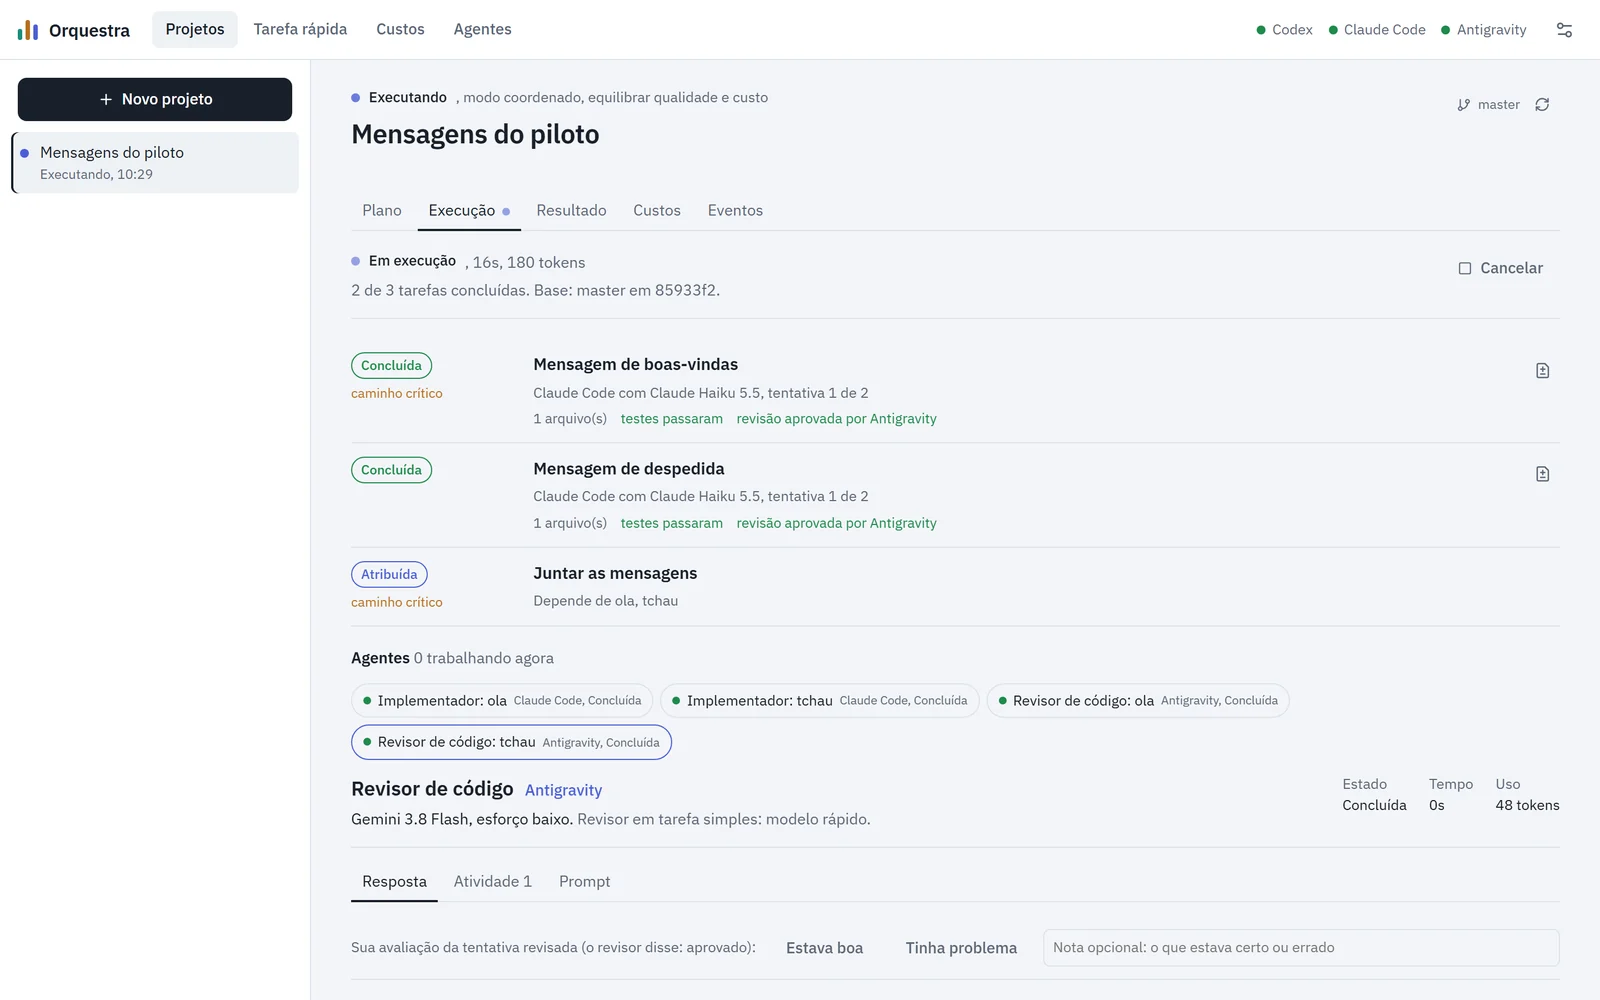
As in a musical score, each task has its own line: it leaves the integration line, goes through the tests and the review, and only then returns to it.
- Plan
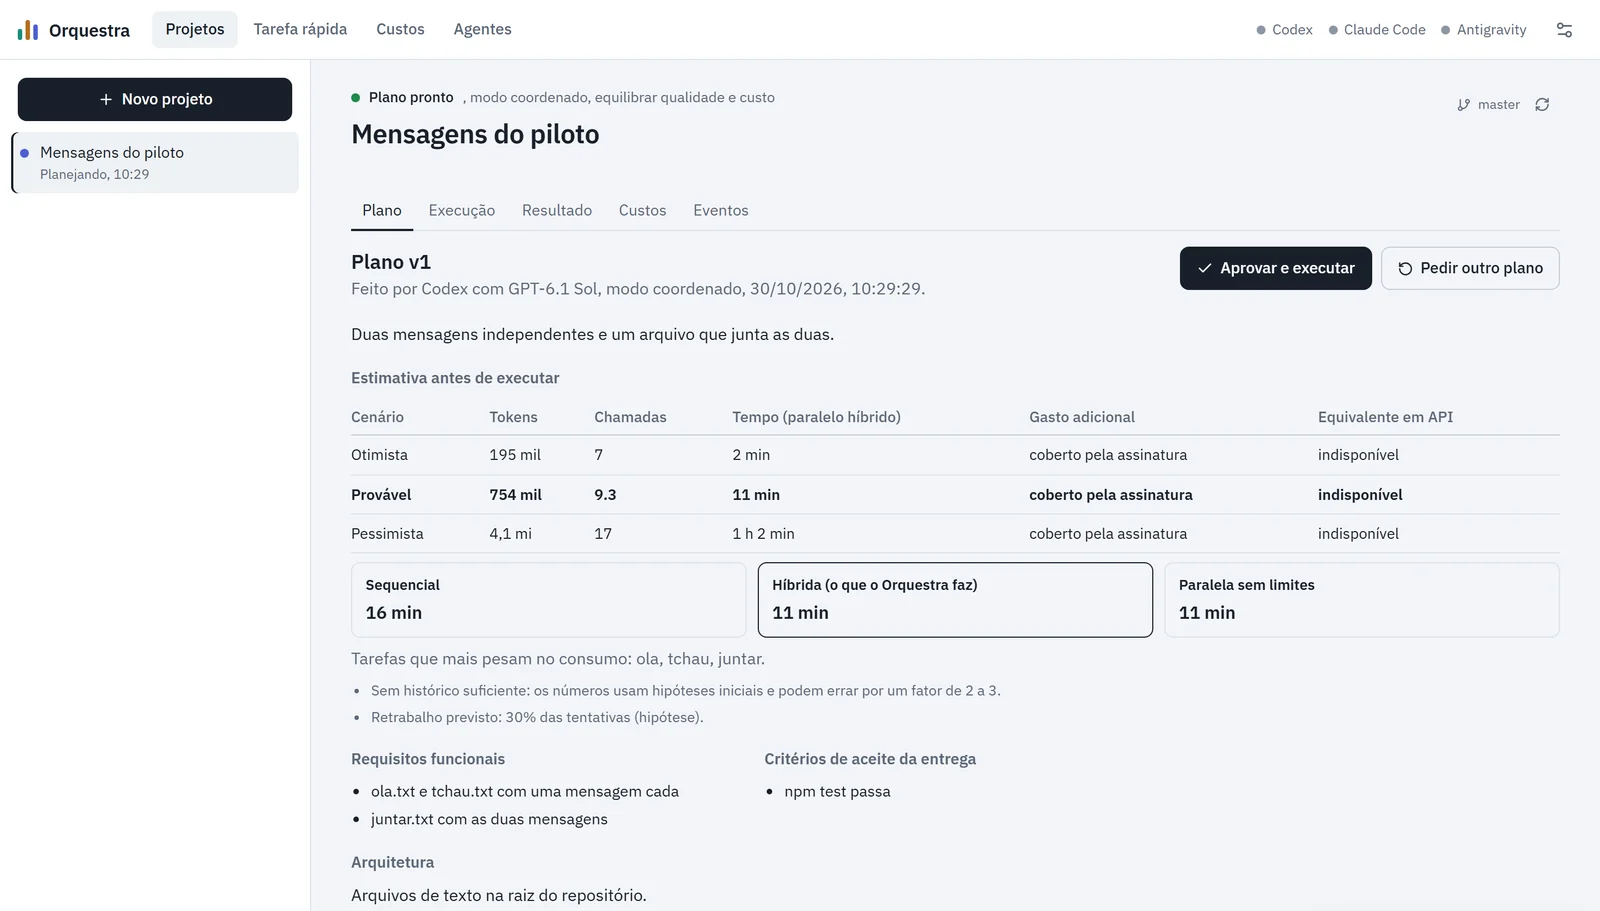
The planner reads a snapshot of the folder, without .env or keys, and returns tasks as JSON; the code validates the dependencies, and the person approves.
JSON - Copies
Each ready task gets its own worktree and branch; tasks that share files do not run together.
Gitup to 4 in parallel - Tests
The implementer edits the files and Orquestra runs the project's tests; if they fail, the output goes back to the implementer.
npm test - Review
An agent from another vendor reads the diff and the automatic checks, and ends with APPROVED or CHANGES.
- Integration
Only the approved task goes in, one at a time, with the tests after each merge.
merge --no-ff - Delivery
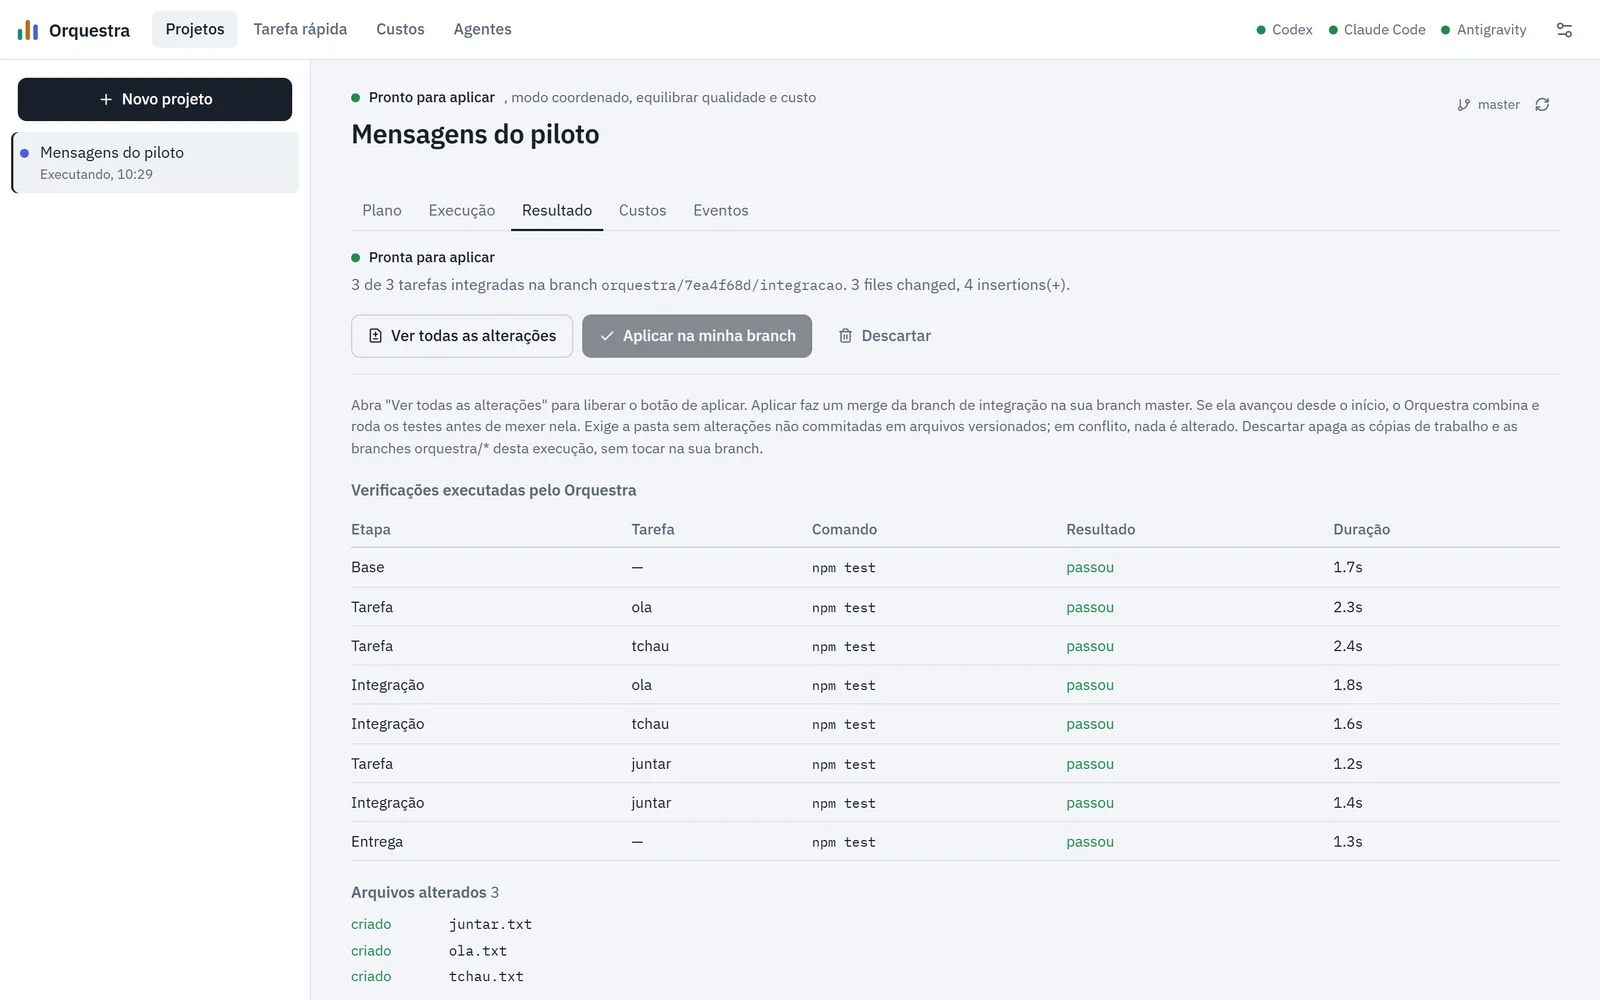
The tests run on the full integration; the person's branch only changes when they open the changes and apply.
The model comes in at defined points, and what it returns is validated: states, scheduling, isolation, tests and integration are code. Beside it, a plan task as the planner delivers it.
No task is done because the agent said so. The reviewer is never from the vendor that implemented it, and with no reviewer available the task stops.
{
  "id": "juntar",
  "title": "Juntar as mensagens",
  "dependsOn": ["ola", "tchau"],
  "files": ["juntar.txt"],
  "acceptance": ["juntar.txt existe"]
}
Decisions
Instead of: A multi-agent framework in which the model drives the flow.
Cost accepted: More of my own code for states, scheduling and integration.
Instead of: Agents editing the same folder at the same time.
Cost accepted: Requires a repository with at least one commit; on Windows, short names to stay under Git's path limit.
Instead of: The same agent checking its own work.
Cost accepted: One more call per task, and the task stops when no reviewer is available.
Instead of: Merging everything at the end and resolving the conflicts all at once.
Cost accepted: Integration becomes a queue, with the tests after each merge.
Instead of: Calling the APIs and paying per token.
Cost accepted: It depends on each plan's quota; when one runs out, the role passes to the next agent in line.
Instead of: Filling in with an estimate what the CLI does not report.
Cost accepted: Screens with stated gaps; the API equivalent only appears with a registered price, with source and date.
How it was built
- Oct 19The three real CLIs
The demo becomes real execution through Codex, Claude Code and Antigravity, with model choice by role.
- Oct 19Project mode
Validated plan, tasks with dependencies, parallel worktrees, cross-review and queued integration.
- Oct 19The first real run
Four tasks, 10 calls and no failures; the real agents reveal 5 defects the simulated ones did not show.
- Oct 19The external review
Two independent reviews, each claim checked against the code before accepting; 6 were wrong or imprecise.
- Oct 20Version 0.7.1
The second review round and the live validation with the three CLIs, with 8 of 8 checks.
I designed and built it by directing Claude Code and Codex, with the tests and reviews as the gate. Each defect seen live was recorded in the test plan, with the fix and the test that covers it.
Today and next
Today
The 0.7.1 base runs on my computer with the three CLIs. Orquestra keeps changing; this page describes the main cycle, which is what has been validated live.
Next
- An end-to-end run on a real project, from the plan to applying the result.
- Validate the advanced mode live, with the analyst that asks questions, the security reviewer and a real conflict resolved in integration.
- Label 30 to 50 real reviews to measure how often the reviewer is right, before changing its prompt.
The images are of the interface running the test suite's synthetic project, with a simulated agent in place of the CLIs: the model names shown in them come from the catalog, not from a real run.